Collect and classify files
Bring documents in through uploads, inboxes or storage connections. Identify supported document types and send each file to the right workflow.
Intelligent document processing · Custom software
Turn incoming documents into data your team can use. Digittrix builds custom AI document processing software that reads files, extracts key fields and checks the results. Review exceptions in one workspace, then send approved records to your ERP, CRM or document system.
Built around your workflow
Integrated with your operation
Tested with your team
The service, explained
Intelligent document processing (IDP) combines optical character recognition (OCR), document classification and data extraction with validation and human review. We build this workflow around your documents, required fields and approval rules, then connect it to the systems your team uses.
What we build
Choose the features your team needs. We agree the scope, system connections and success criteria before development.
Bring documents in through uploads, inboxes or storage connections. Identify supported document types and send each file to the right workflow.
Read text, tables and agreed fields from PDFs, scans and images. Map the results to the record format your business needs.
Validate required fields, totals and formats. Flag duplicates and compare extracted values with reference data where your systems provide access.
Show the document beside its extracted fields. Let staff correct values, resolve missing information and approve records before release.
Send approved data to your ERP, CRM or document management system through supported APIs or exports. Track failed transfers and retries.
Monitor batches, review queues and integration failures. Give users appropriate permissions and keep a history of corrections and approvals.
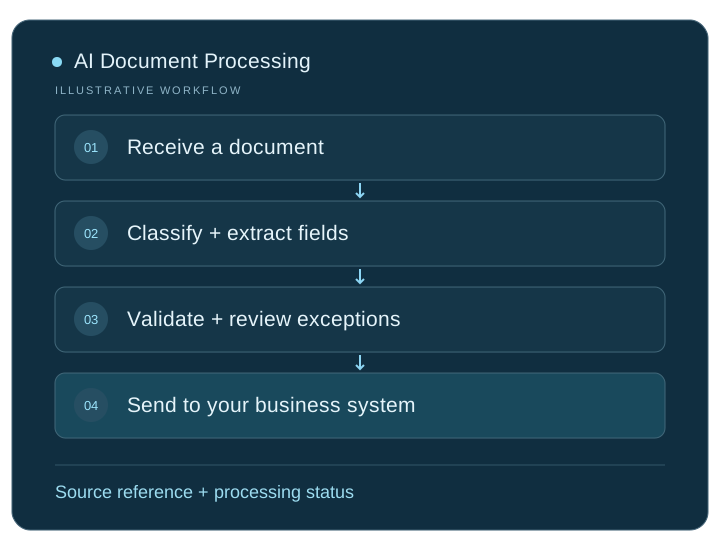
How the software works
Check the format and quality of documents from agreed sources.
Identify the document type and capture its required fields.
Apply business checks and send exceptions to the right reviewer.
Deliver approved records and keep a traceable status for each file.
Connect the complete workflow
We check access, compatibility and data ownership early. Each connection needs clear rules for permissions, failed requests and recovery.
| Connection | What we connect | What we check first |
|---|---|---|
| Document sources | Uploads, email inboxes and file storage | Access permissions, formats and expected batch sizes |
| Business data | Supplier lists, purchase orders and validation rules | Reference data, matching rules and approval ownership |
| Destination systems | ERP, CRM and document management platforms | Field mappings, supported APIs and failure recovery |
Test before you roll out
We agree measurable targets with your team and test representative inputs, including the difficult cases.
Compare extracted values with a manually checked sample, reporting results by document type and field rather than only one overall number.
Test missing fields, inconsistent totals and duplicate files; confirm uncertain results enter the correct review queue.
Measure processing time and review effort, then check approved records reach the destination with traceable failures and retries.
Scope, cost and delivery
Start with a representative document set and a list of required fields. We test the difficult cases early, then plan the application and system connections.
We provide a project-specific estimate and milestones after discovery. Your proposal separates development from ongoing operating costs.
Get a project estimateWe agree source-code and licence terms, deployment access, documentation, team training and support responsibilities in your proposal.
Map the workflow, inputs and system connections.
Test the core task and agree acceptance targets.
Build the application, integrations and admin tools.
Validate, deploy, train your team and start agreed support.
Your development partner
Digittrix Infotech Private Limited builds business software from Mohali, India. Explore our team, published work and client feedback as you choose your development partner.
Answers before you build
Yes. We build around your document types, required fields, validation rules and approval steps. We can deliver a standalone platform or add document processing to your existing application.
OCR turns text in scans and images into machine-readable text. IDP adds document classification, structured field extraction, validation, human review and delivery to business systems.
We assess your sample files before confirming coverage. Common starting points include PDFs, scanned invoices, purchase orders, delivery records and forms. Tables, handwriting and different languages need specific testing.
Yes, where your system provides suitable APIs or import options. We map the fields, set access permissions and handle transfer failures so staff can trace each approved record.
The level of automation depends on document quality, variation and business rules. We use pilot results to set review thresholds and keep uncertain or invalid data out of final records.
We assess your cloud or on-site environment alongside the OCR and AI components. We agree storage, retention, permissions and any external processing before selecting the architecture.
Document variety, field complexity, volume, integrations and review tools determine the estimate. We provide a project proposal after discovery and use a pilot to test uncertain requirements.
Let’s plan your project
Tell us what comes in, which fields matter and where approved data needs to go. We’ll help define the build.
Service information updated .